Low-cost batch inference with audit logging and spend management
Submit a job, collect every result within 24 hours, and pay less than OpenRouter batch inference. Track token usage and cost per user, set spend limits, and keep a full audit trail. Request bodies from the Laravel AI SDK, Prism PHP, and LangChain drop in unchanged.
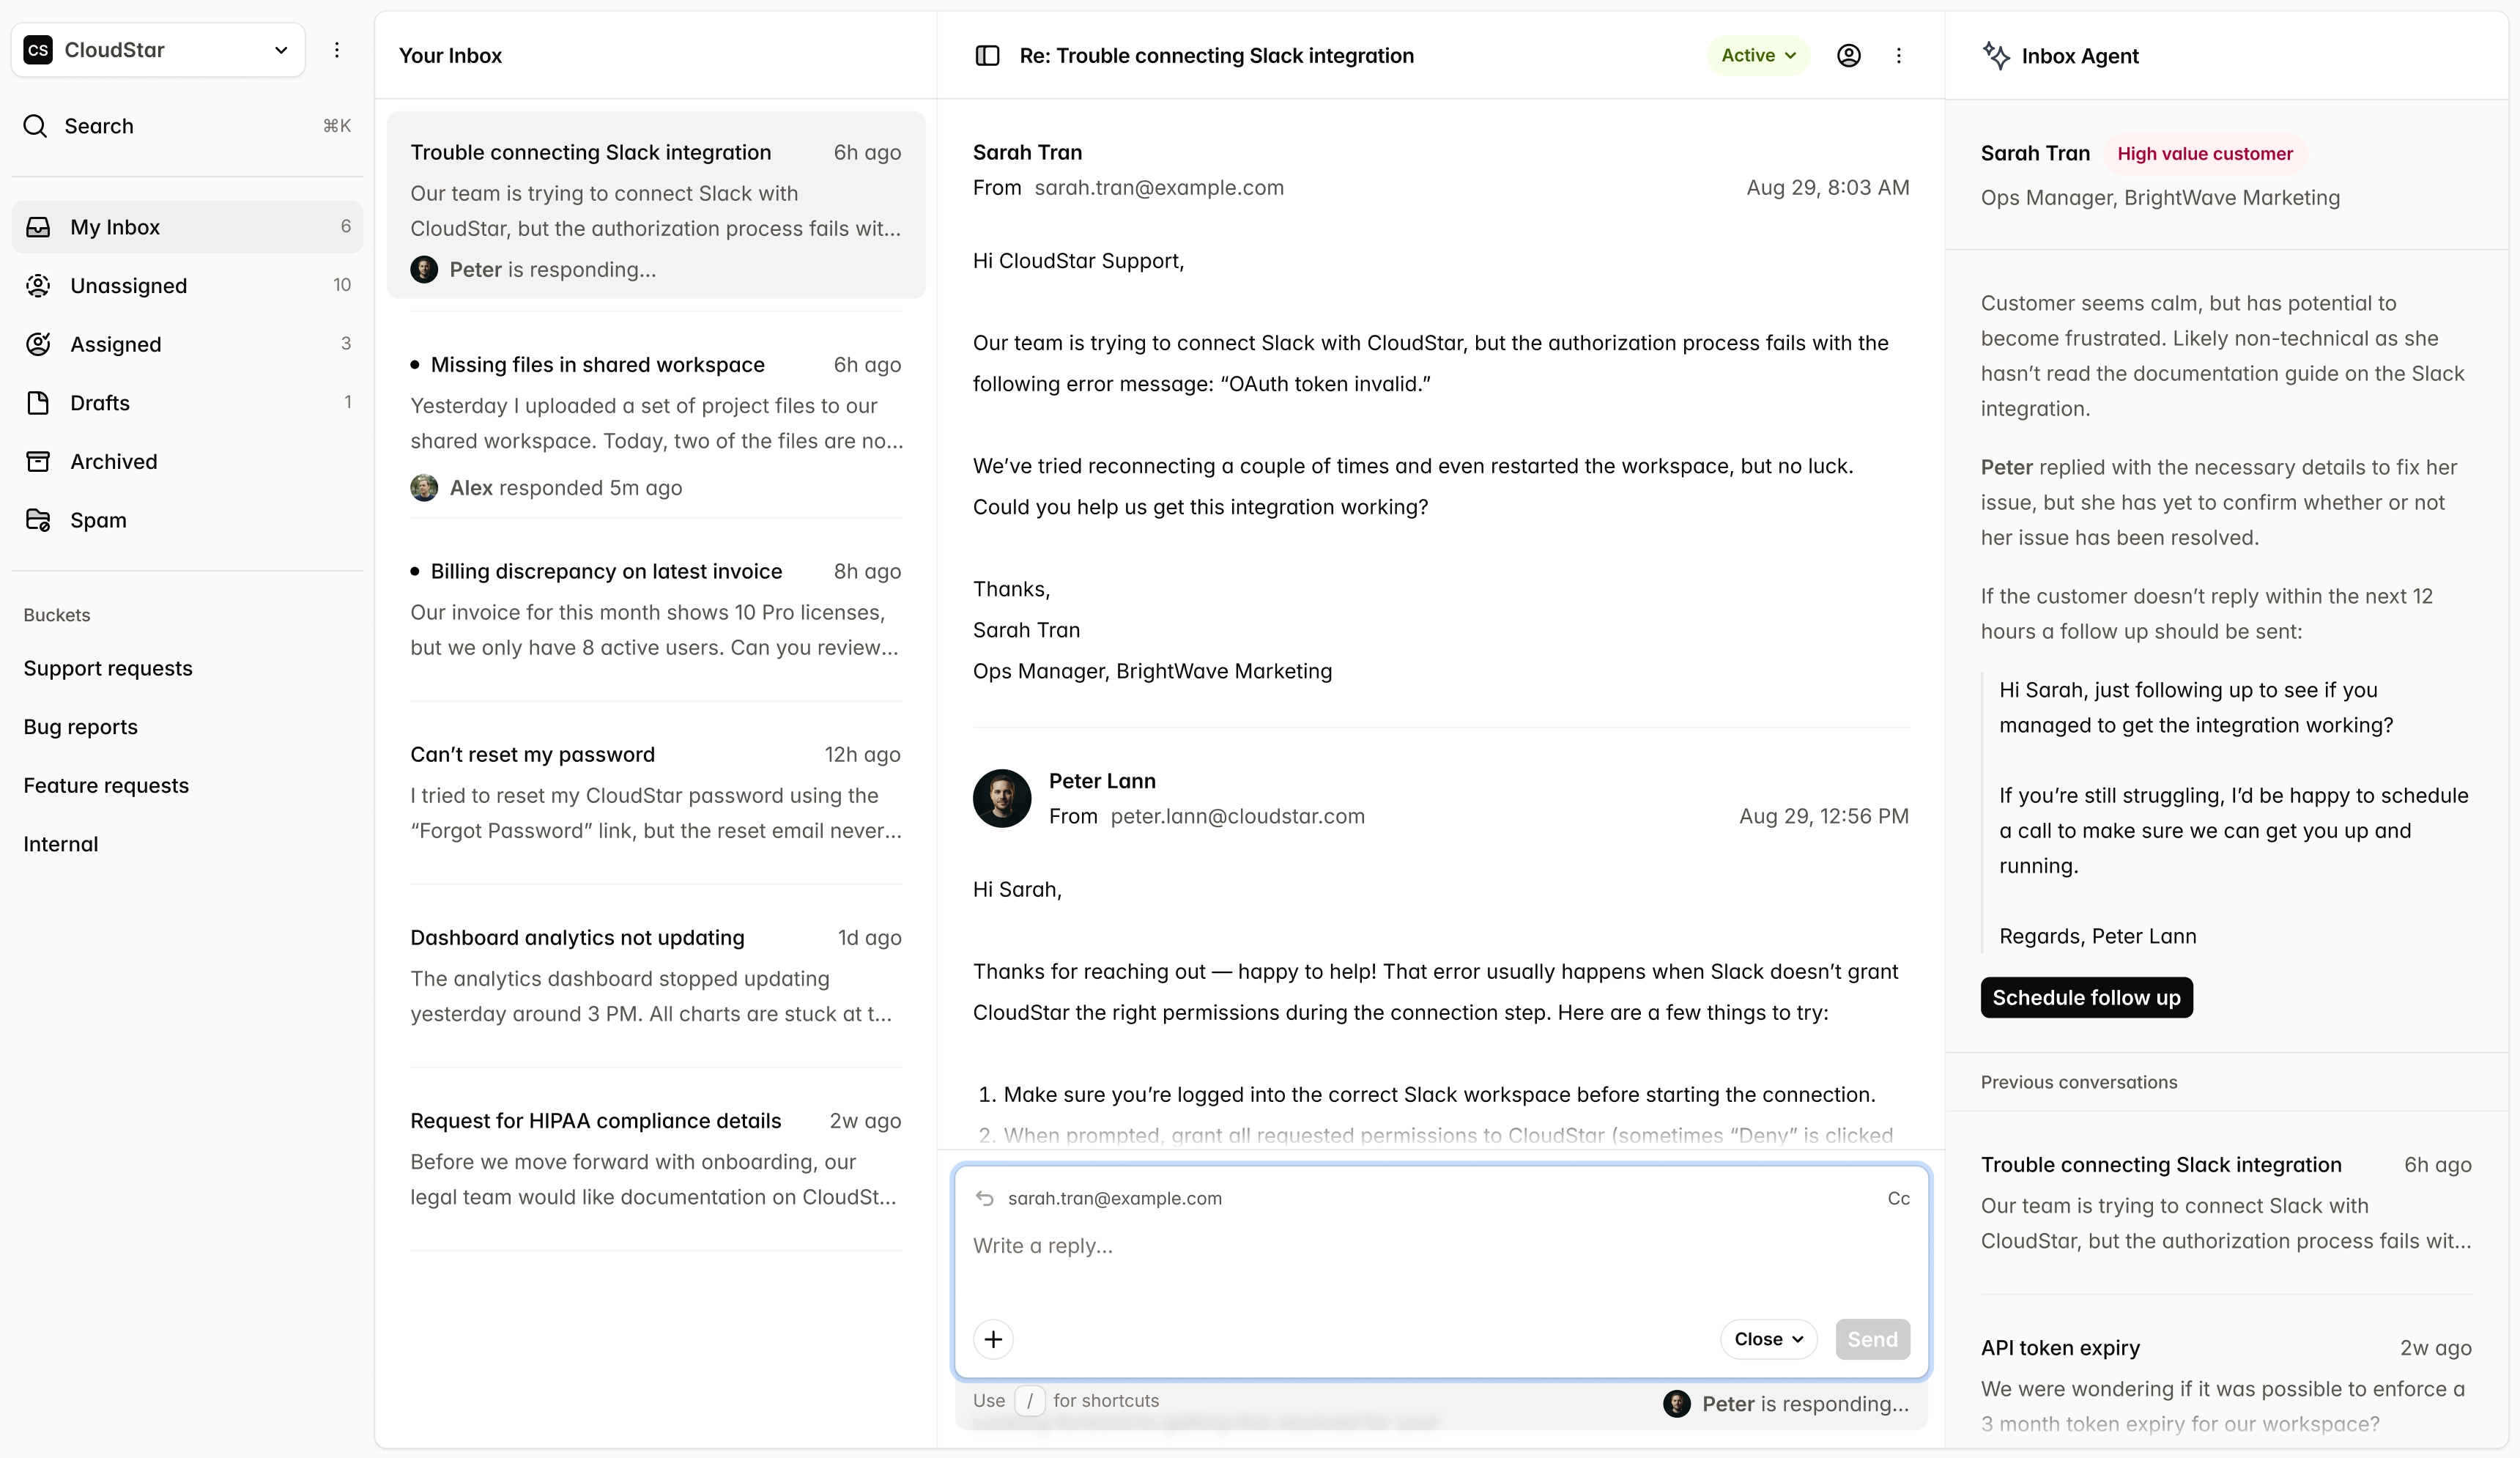
Every model behind one jobs API, with built-in logging and usage tracking
Change the model name on a request and everything else stays put: tokens and cost per user, spend limits per user, an audit log of every call, and 90 days of conversation history.
Switch models in one line
Change the model name and you're on a different model. Every line of a job is an ordinary OpenAI request, so the payloads your app already builds go in unchanged.
Track usage per customer
Tokens and dollars broken down by user, not one lump sum you get to explain at the end of the month.
Usage limits per customer
Set a usage cap on any user so one runaway account can't quietly spend your whole budget.
Full audit logging
Every call is recorded: who asked, which model answered, what came back, and what it cost.
Conversation history
Read whole threads back, not just single calls. 90 days on Pay-as-you-go, 13 months on Enterprise.
Regional support and data residency
Run in the US, EU, or India. Pick what's closest to your users and where you need data to live.
A true jobs API, built for asynchronous workloads
Upload a file of requests, submit one job, and collect every result within 24 hours. Batch inference is priced below OpenRouter batch inference.
One job, not thousands of calls
Put up to 50,000 requests in a single file. One call to submit it, one to check on it, one to collect the results.
24-hour completion window
A ceiling, not an estimate. Most jobs finish well inside it, and Enterprise runs on a 4-hour window.
Lower pricing than OpenRouter batch
One rate per model, priced below OpenRouter batch inference. There is no interactive tier to pay a premium for.
Track token usage and spend per customer with our Billing API
Tag every request in a job, attribute it to your internal ID, and read the numbers back from the Billing API. Set usage limits and keep your agents profitable for every customer.
Cost per user, not per month
Attribute every line of a job to a user or billable entity with tags, then pull tokens and spend for any of them out of the Billing API. Pricing is per million tokens, so your margins aren't a mystery.
Set usage limits per customer or plan
Give any user a usage limit. Once they hit it, Lararouter returns a 402 Payment Required status to prevent unexpected costs for your application.
Priced per million tokens, plus a monthly plan fee.
One rate per model, priced per million input and output tokens. Enterprise adds a 4-hour completion window, 13-month data retention, SSO, and a 99.9% uptime SLA on top.
Pay-as-you-go
$15/month + usage
$15 per month plus the input and output tokens you use. No annual contract.
Every model behind one jobs API
Per-entity usage & cost tracking
Per-entity usage limits
Full audit logging
90-day data retention
24-hour completion window
OpenAI-compatible request bodies
US, EU, and India regions
Enterprise
$250/month + usage
For teams that have to pass a security review and prove uptime in writing.
Everything in Pay-as-you-go
4-hour completion window
Single Sign-On (OIDC and SAML)
13-month data retention
99.9% uptime SLA
Questions & Answers
Schedule a demo and get $50 in Free Credits
Meet with our integration team to discuss how you plan to use Lararouter with your application and get $50 in free credits on us.